Affiliate disclosure: AI Tools Vetted is reader-supported and may show ads on this page (including Adcash). NVIDIA doesn’t pay us and has no affiliate program with us, so every NVIDIA, Hugging Face and tool link here is a plain link. One sponsored link sits in a separate “Tools we use alongside” box at the end; it isn’t part of this explainer.
Last updated October 18, 2026 · Specs, availability and license checked October 18, 2026 on NVIDIA’s official pages and model cards.
TL;DR
TL;DR
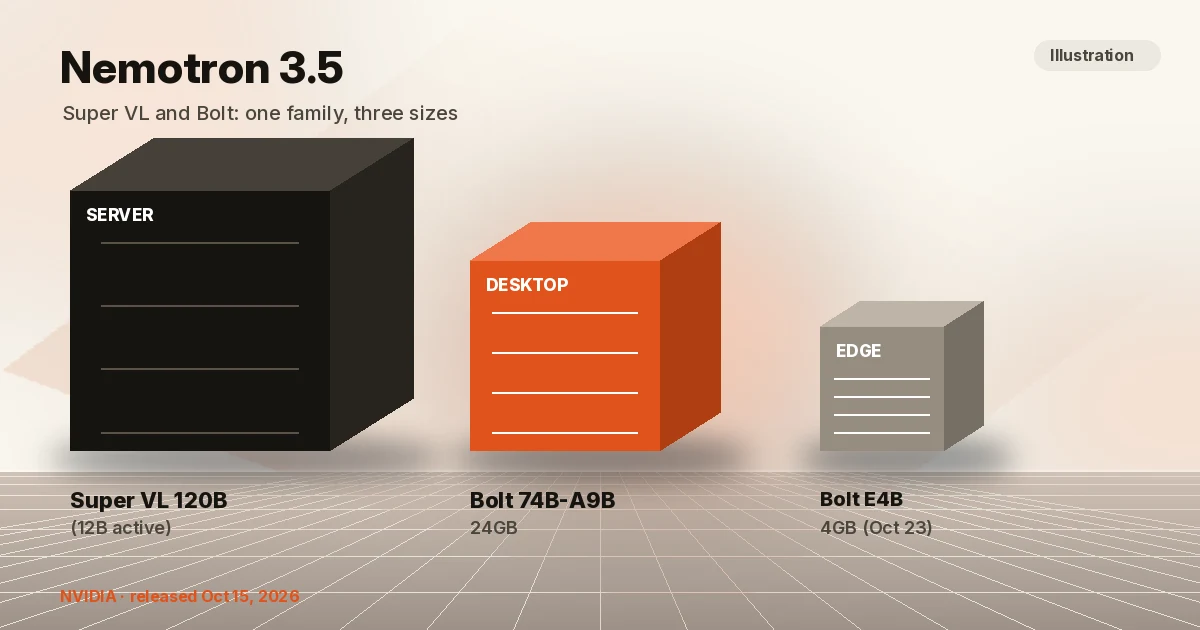
- What’s new: On October 15, 2026, NVIDIA released Nemotron 3.5 Super VL (120B parameters, 12B active) and Bolt 74B-A9B 24GB. A third model, Bolt E4B 4GB, is “coming Oct. 23.”
- Open: weights, datasets and training recipes are published, under the permissive OpenMDW-1.1 license, for commercial or non-commercial use.
- Hardware reality: “24GB” is the size of Bolt’s weights. NVIDIA’s own llama.cpp recipes start at a 32 GB graphics card or a 64 GB RTX Spark.
- We haven’t run them. Every benchmark below is NVIDIA’s.
What NVIDIA released
NVIDIA announced the models in a blog post by Kari Briski on October 15, 2026 (NVIDIA blog). Super VL is “an open 120-billion-parameter model” for “specialized always-on agents.” The two Bolt models are edge models: Bolt 74B-A9B 24GB “for local agentic workloads,” and Bolt E4B 4GB “for fast conversational agents.” Super VL and Bolt 74B-A9B were available the same day.
If you searched for “Nemotron 3.5 Lightning,” it isn’t part of this launch. NVIDIA’s post says Lightning was “released in August” for high-throughput work, and Super VL and Bolt now join it and Ultra in the Nemotron family.
Super VL vs Bolt 74B-A9B vs Bolt E4B
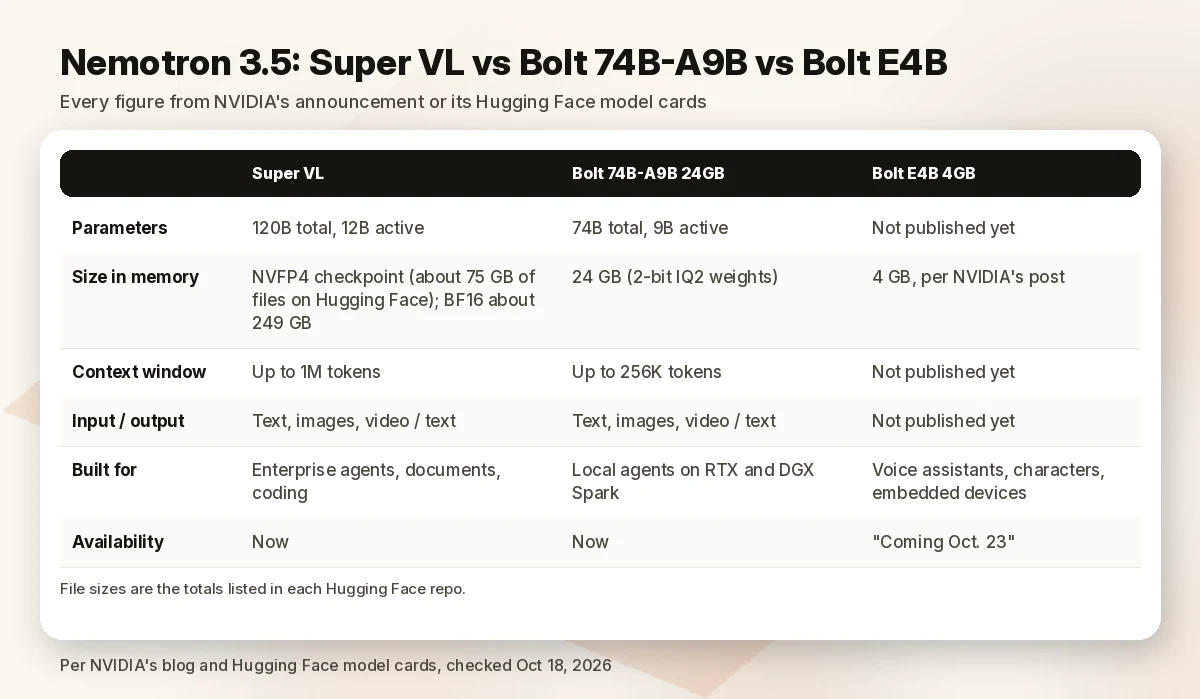
Every figure here comes from NVIDIA’s announcement or its Hugging Face model cards, checked October 18, 2026.
| Nemotron 3.5 Super VL | Nemotron 3.5 Bolt 74B-A9B 24GB | Nemotron 3.5 Bolt E4B 4GB | |
|---|---|---|---|
| Parameters | 120B total, 12B active | 74B total, 9B active | Not published yet |
| Size in memory | NVFP4 checkpoint (about 75 GB of files on Hugging Face); BF16 about 249 GB | 24 GB (2-bit IQ2 weights) | 4 GB, per NVIDIA’s post |
| Context window | Up to 1M tokens | Up to 256K tokens | Not published yet |
| Input / output | Text, images, video / text | Text, images, video / text | Not published yet |
| Built for | Enterprise agents, documents, coding | Local agents on RTX and DGX Spark | Voice assistants, characters, embedded devices |
| Availability | Now | Now | “Coming Oct. 23” |
| License | OpenMDW-1.1 | OpenMDW-1.1 | Not published yet |
Sources: Super VL NVFP4 model card, Bolt 74B-A9B model card, NVIDIA blog. File sizes are the totals listed in each Hugging Face repo.
Bolt is a smaller copy of Super VL, not a separate design. NVIDIA compressed the 120B-A12B parent to 74B-A9B with its Star Elastic method, then quantized the experts to 2.0625 bits per weight to fit the 24 GB budget (Bolt technical page). The Bolt card lists Brazilian Portuguese, Hindi, Korean and Chinese among supported input languages, with a post-training data cutoff of May 2026.
What NVIDIA’s benchmarks claim
These are NVIDIA’s numbers, not ours:
- Super VL: NVIDIA reports up to “5x faster” throughput than other open models in its class on a single GPU, and scores of 63.44% on Hermes Bench and 87.05% on LangChain evals, ahead of its own Nemotron 3 Ultra (developer blog). Its model card lists 71.10 on SWE-bench Verified (BF16).
- Bolt 74B-A9B: NVIDIA calls it “#1 in PinchBench” and “#2 in BrowseComp” among models with a similar memory footprint. Its own table is closer than that headline: 87.82 on PinchBench against 88.07 for Qwen3.6-35B-A3B.
- Speed trade-off: on an RTX Spark laptop, NVIDIA measured Bolt at 83.99 tokens per second, slower than Qwen3.6 35B-A3B (96.63) and Gemma 4 26B-A4B (100.56) in the same table. NVIDIA’s pitch is more accuracy per GB, not raw speed.
Where to get them
- Super VL: Hugging Face (BF16, NVFP4 and base checkpoints), OpenRouter, ModelScope and NVIDIA NIM, per NVIDIA’s post. NVIDIA’s API catalog also offers a “free API endpoint” for prototyping (build.nvidia.com).
- Bolt 74B-A9B: Hugging Face, in standard and GGUF formats, with support in llama.cpp, Ollama, LM Studio, Unsloth and vLLM (Bolt GGUF card).
- Bolt E4B: nothing to download until October 23. NVIDIA hasn’t posted a model card yet.
The Hugging Face repos weren’t gated when we checked, so no access request is needed.
Which one fits your hardware
This section is our reading of NVIDIA’s published requirements, not a test.
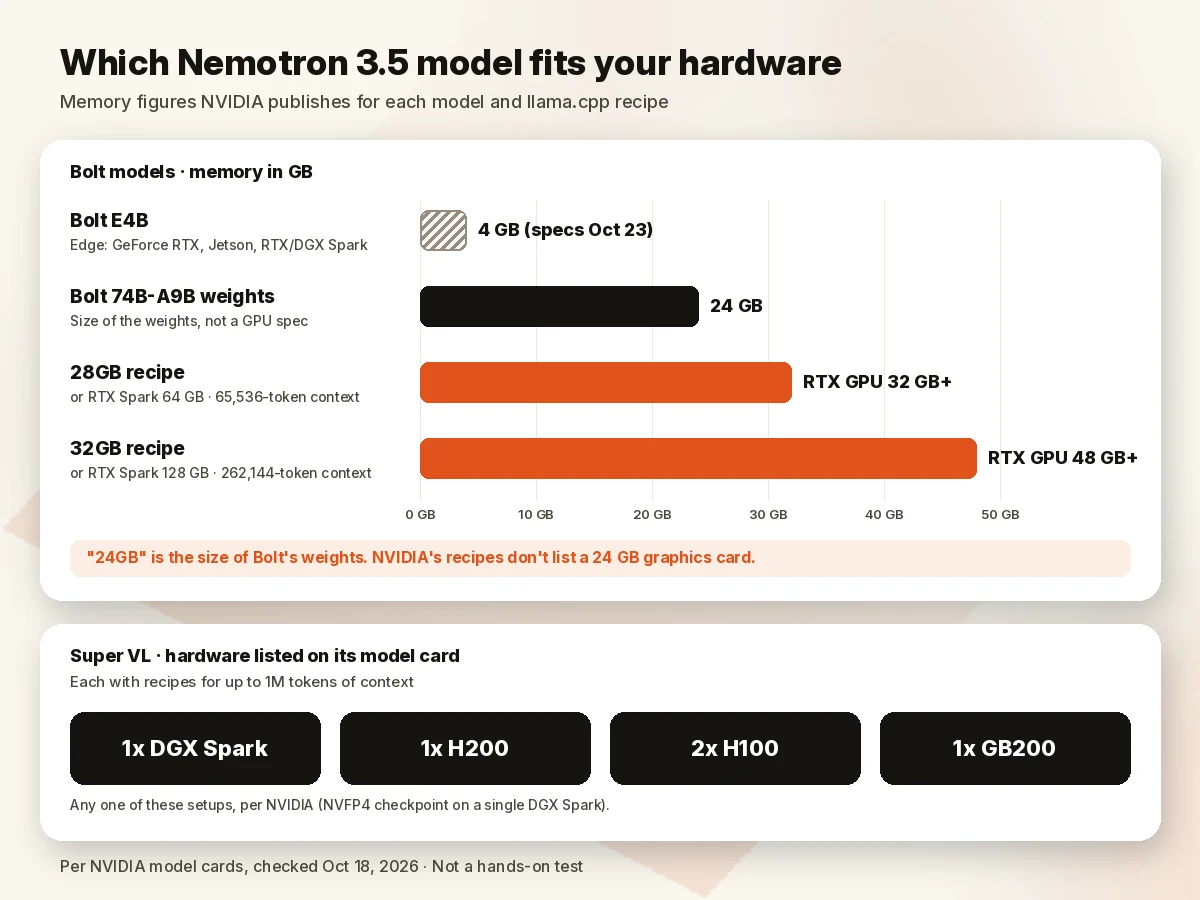
A gaming PC or laptop: look at Bolt 74B-A9B, but read the fine print. The weights are 24 GB, yet NVIDIA’s llama.cpp recipes call for more memory than that, because context and the speculative-decoding drafter need room too (Bolt GGUF card):
| NVIDIA recipe | Hardware NVIDIA lists | Context |
|---|---|---|
| 28GB recipe | RTX Spark 64 GB or an RTX graphics card with 32 GB+ | 65,536 tokens |
| 32GB recipe | RTX Spark 128 GB or an RTX graphics card with 48 GB+ | 262,144 tokens |
NVIDIA lists the GeForce RTX 5090 among Bolt’s test hardware. It doesn’t list a 24 GB card such as the RTX 4090 in either recipe, so don’t assume “24GB” means a 24 GB GPU is enough.
An RTX Spark laptop or DGX Spark: this is what Bolt was built for. NVIDIA says Bolt targets “RTX Spark laptops arriving Oct. 16.” NVIDIA says those laptops, available since October 16, come with up to 128 GB of unified memory and start at $2,399 (NVIDIA newsroom, NVIDIA blog, Oct 17). Its newsroom says Bolt runs on “supported RTX Spark configurations,” so check the memory of the model you buy. Super VL also runs on a single DGX Spark with the NVFP4 checkpoint, per its model card.
Servers: Super VL’s model card lists 1× DGX Spark, 1× H200, 2× H100 or 1× GB200, each with recipes for up to 1M tokens of context.
Small devices: wait for Bolt E4B. NVIDIA says the 4 GB model is for GeForce RTX, Jetson and RTX/DGX Spark, but hasn’t published its specs.
What this changes for you
- Developers building agents get a fully open option with a 1M-token context that they can fine-tune with NVIDIA NeMo, using open datasets NVIDIA released alongside it.
- Local-AI hobbyists get a 74B-parameter model that NVIDIA says beats 4-bit models of similar size on accuracy, at a 32 GB-class hardware bar, and trades some speed for that accuracy.
- Teams already on hosted APIs can try Super VL through NVIDIA’s free prototyping endpoint or OpenRouter before deciding to self-host.
For a far bigger open model with very different hardware needs, see our explainer on Muse Spark Open. For a hosted model built for cheap, short API calls, see our Claude Haiku 5.5 review, and for Google’s latest app model, our Gemini 4 Argon guide.
Unknowns
- Bolt E4B specs and license: not officially specified before October 23.
- Hosted prices: NVIDIA doesn’t publish per-token prices for OpenRouter or other providers. Check the provider’s own page.
- Conflicting official figures: NVIDIA’s API catalog lists Super VL at “124B” parameters with a 262K context, labeled “early-access,” while NVIDIA’s model card says 120B and up to 1M tokens. NVIDIA hasn’t explained the difference; the catalog page may still be in transition. We’ll update this when the pages match.
- Independent benchmarks: none yet that we’d cite.
How we evaluated
We read NVIDIA’s announcement, developer blog, Bolt technical page, newsroom and API catalog, plus the official Hugging Face model cards and the OpenMDW-1.1 license, on October 18, 2026. We didn’t run the models. Benchmarks are attributed to NVIDIA, and file sizes are the totals listed in NVIDIA’s Hugging Face repos.
FAQ
What is Nemotron 3.5 Super VL? NVIDIA’s open vision-language model for agents: 120B total parameters, 12B active, up to 1M tokens of context, reading text, images and video. NVIDIA released it on October 15, 2026.
Can I run Nemotron 3.5 Bolt locally? Yes, Bolt 74B-A9B is built for that, through llama.cpp, Ollama, LM Studio, Unsloth or vLLM. NVIDIA’s llama.cpp recipes call for an RTX Spark with 64 GB or 128 GB, or an RTX graphics card with 32 GB or more.
When is Bolt E4B available? NVIDIA says October 23, 2026.
Is Nemotron 3.5 open? Yes. NVIDIA publishes the weights, datasets and training recipes, and the models use the OpenMDW-1.1 license, which allows commercial use. You must keep a copy of the license and the original notices when you redistribute the weights.
Is Nemotron 3.5 Lightning new? No. NVIDIA says Lightning came out in August; the October launch added Super VL and Bolt.
Sources (official pages, checked on October 18, 2026, ~01:20 BRT)
- NVIDIA blog announcement (Oct 15, 2026, Kari Briski): https://blogs.nvidia.com/blog/nemotron-3-5-super-vl/
- NVIDIA developer blog (Oct 15, 2026): https://developer.nvidia.com/blog/nvidia-nemotron-3-5-super-vl-powers-specialized-agents-with-multimodal-reasoning/
- NVIDIA research, Bolt 74B-A9B 24GB technical page (Oct 15, 2026): https://research.nvidia.com/labs/nemotron/Nemotron-3.5-Bolt-24GB/
- Super VL NVFP4 model card: https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4 · BF16: https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16
- Bolt 74B-A9B 24GB model card: https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB · GGUF: https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF
- NVIDIA API catalog (Super VL): https://build.nvidia.com/nvidia/nemotron-3.5-super-vl-120b-a12b
- NVIDIA newsroom, RTX Spark availability (Oct 16, 2026): https://nvidianews.nvidia.com/news/nvidia-rtx-spark-pcs-available-today-a-new-beginning-for-windows-pcs
- NVIDIA blog, RTX Spark laptops from $2,399 (Oct 17, 2026): https://blogs.nvidia.com/blog/local-ai-rtx-spark-windows-laptops-celebration/
- OpenMDW-1.1 license: https://openmdw.ai/license/1-1/
Tools we use alongside (outside this explainer; not related to NVIDIA)
If you publish about AI models for search traffic, Semrush is the keyword and competitor research suite we use. The link below is sponsored; the NVIDIA and Hugging Face links above are not.